Work
Research and engineering projects, newest first. Each page covers the approach, the numbers, and what didn't hold up.
AgentSwarm: teams of small agents, gated by a calibrated judge
Independent teams of agents (executor, tester, red team, planner) move work up maturity levels on git branches, through gates. Teams never call each other, so nothing can deadlock. Language models produce, a calibrated judge decides, plain code controls.
Planning through a learned world model
A JEPA world model trained from pixels on dm_control's ball-in-cup, driven by a CEM/MPC planner. Built from scratch to learn the whole loop: self-supervised pretraining, probing what the latent actually knows, and planning through it.
Hyperbolic latents for branching futures
Does hyperbolic geometry help a predictor represent futures that fork? Tested on a grid maze against an identical Euclidean baseline. Answer so far: yes at low latent dimension, and it reverses at high dimension.
Multi-engine OCR for title documents
Verbatim text from scanned deeds, mortgages and plats. LLM vision for prose and layout, pixel OCR for numbers, and a reconcile step checked by domain verifiers.
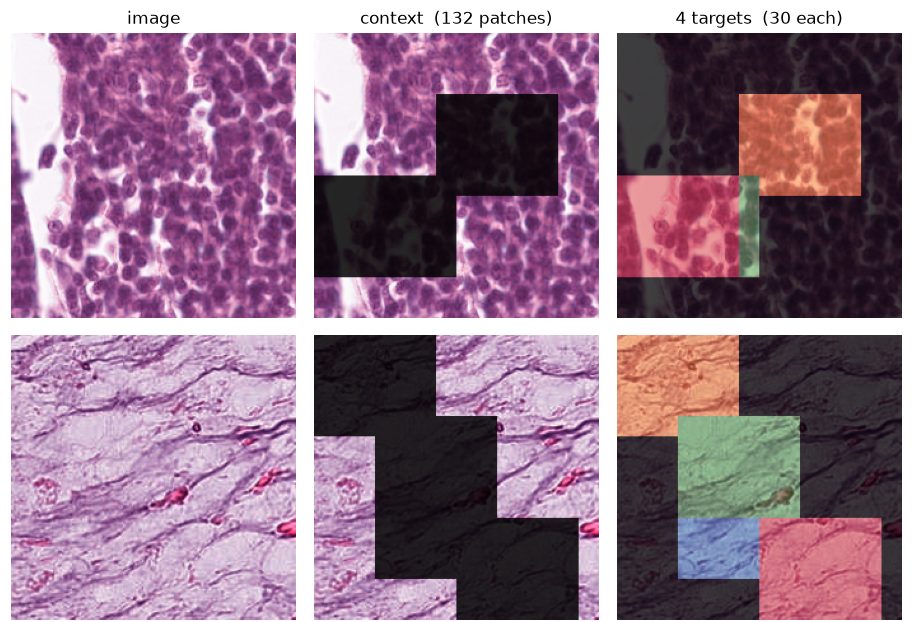
I-JEPA on histology images
Image JEPA (ViT, block masking) pretrained on PathMNIST at 224px on a 24 GB Mac, then frozen-feature probes against a random-init encoder to measure what self-supervision actually buys.
Governed agent systems
Years of building LLM agents that can be audited: typed state, planner–worker–critic loops, adversarial review. What worked, what didn't, and what carried over.